"Will I lose data moving to a new CRM?" is the question underneath almost every CRM data migration search, and most guides answer it the same reassuring way: map your fields, run a test import, and you'll be fine. That answer is not wrong, but it skips the part that actually matters once real client data is involved: what a given platform does the moment it finds a record that looks like it might already exist.
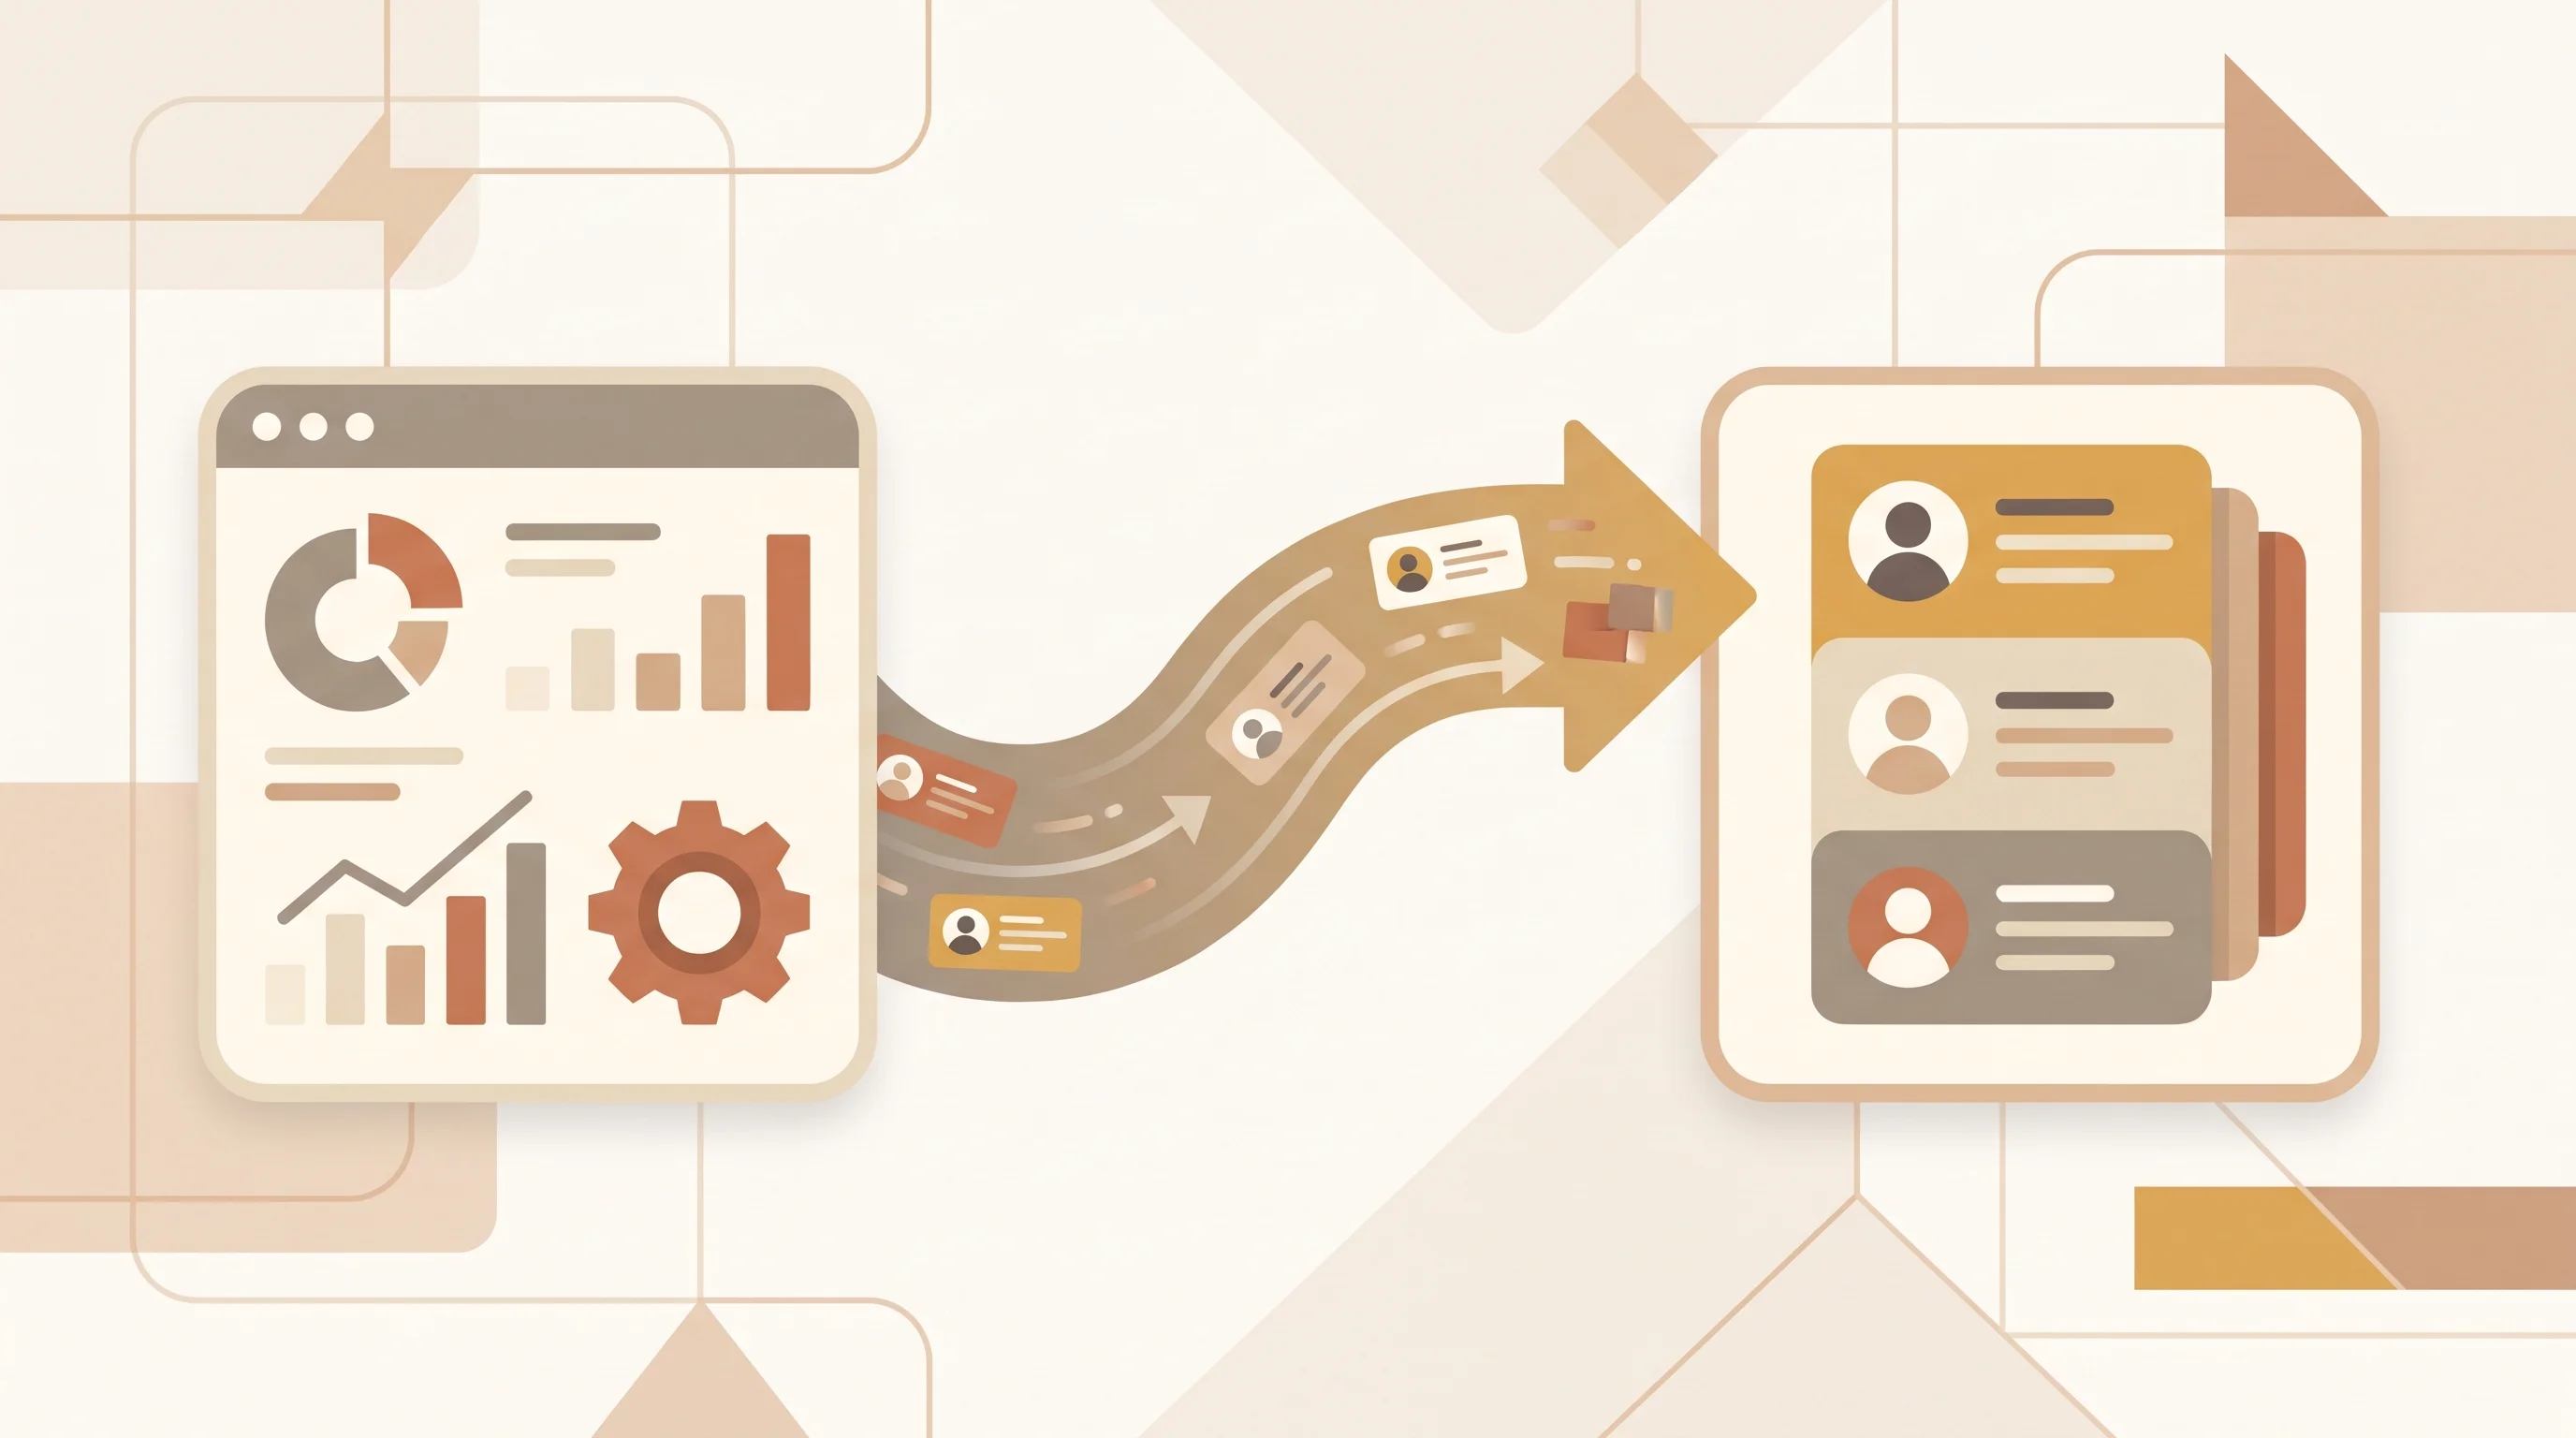
GoHighLevel's own import documentation answers that question for a HubSpot-to-HighLevel move in one plain sentence: "By default, no. Imported records are added alongside whatever's already in your account." HubSpot's own import documentation takes the opposite default: it requires "a unique identifier to update records, avoid creating duplicate records." Two CRMs that show up constantly in the same agency stack handle the exact same scenario in opposite ways, and neither behavior is a bug. It is each platform's documented default.
What "migrated" means depends on which platform receives the data
Most CRM data migration guides treat the destination system as a neutral container: data goes in, data comes out the same shape. In practice, the receiving platform's own default behavior decides what a "clean" migration even looks like.
On GoHighLevel's side, the HubSpot importer is explicit that duplicate-blocking should be turned off before you start, because leaving it on "causes a lot of avoidable errors during a HubSpot import," according to GoHighLevel's own article. That instruction only makes sense once you know the importer does not try to match an incoming HubSpot contact against an existing HighLevel contact. It adds the new one next to the old one. Run the same import twice, or import into an account that already has manually entered contacts, and the result is two (or more) records for the same person.
HubSpot's own import tool documentation frames the same problem from the other side: a unique identifier field is required specifically "to update records" and "avoid creating duplicate records," per HubSpot's import tool guide. The system is built to expect a match key on every row, not to append first and clean up later.
Neither default is wrong. They are just different, and a migration plan that assumes one platform's behavior while actually moving data into the other produces duplicate records nobody planned for.
The specific things each platform mangles, not just "data loss" in general
"Some data might not transfer perfectly" is true of almost any migration and tells a client nothing useful. The specific, documented failure points are more useful to plan around:
- Calculated fields lose their formula. GoHighLevel's own documentation states plainly that "HubSpot calculated fields are imported as Single Line Text fields" - the number or result carries over once, but the formula behind it does not, so it stops updating the moment the import finishes.
- A conflicting field key can fail the whole mapping. GoHighLevel maps custom fields "based on field keys," and "if a conflicting field key already exists in HighLevel, the import may fail," per the same article. A field that looks identically named in both systems can still collide on the underlying key.
- Recurring tasks are not supported. Stated directly in GoHighLevel's HubSpot import documentation. A recurring follow-up task in HubSpot does not become a recurring task in HighLevel; it either drops or needs to be rebuilt as a one-off.
- An opportunity with no associated contact cannot be imported at all, per the same source, which matters for any deal record that got disconnected from its contact somewhere in the source system before the migration ran.
- Custom properties generally need to exist before the import runs, rather than being created automatically from the file's column headers, on both platforms. GoHighLevel's CSV import documentation is explicit that fields "that do not yet exist in HighLevel" need to be created as custom fields first.
- Workflows and automation logic are not part of what moves. Neither platform's own import documentation lists workflows, sequences, or automations as an imported object type. Pipeline stages and deal records transfer; the logic that moved a deal between those stages automatically does not, and gets rebuilt by hand in the new system.
None of these are exotic edge cases. They are the default, documented behavior of two of the most common CRMs in the agency stack, and every one of them shows up in a real migration sooner or later.
Who eats the cost when one of these shows up after go-live
This is the part a generic migration checklist skips entirely, and it is the part that matters most for a white label CRM migration specifically: when a client calls two weeks after go-live asking why they have three duplicate contacts for their biggest account, or why a follow-up sequence that used to run automatically now does nothing, the client is not asking "which platform's import tool has this limitation." They are asking the agency on the invoice.
Our white label partners resell exactly this kind of migration work alongside chatbots, dashboards, and voice AI builds, under their own brand, which means the platform's documented limitation becomes the agency's support ticket the moment the client notices. A quote that only prices the import step and skips a dedicated test cycle, a duplicate-detection pass, and a list of what will need manual rebuilding (custom fields, workflows, recurring tasks) is pricing half the job.
If the move specifically involves GoHighLevel on the receiving end, our GoHighLevel automation team sets up the sub-account, SaaS Mode, and the duplicate-detection pass as part of the same engagement, so the agency isn't the one discovering the append-not-merge behavior in a client's live account.
A shorter checklist than most guides give you
Three things to confirm before a single real client record moves, not after:
- What does the destination platform do with a record that might already exist? Read that platform's own import documentation for the answer, not a third-party roundup. GoHighLevel appends by default; HubSpot expects a unique identifier. Assume neither until you've confirmed it for the actual pair of systems involved.
- Which fields degrade instead of transferring cleanly? Calculated fields, field-key conflicts, and recurring tasks are the three confirmed casualties on a HubSpot-to-HighLevel move specifically. A different platform pair will have its own list; find it in that platform's own docs before quoting the project.
- What automation logic will need to be rebuilt by hand? If the answer is "most of it," that rebuild time belongs in the quote as its own line item, not folded into "data migration" as if moving records and rebuilding logic were the same task.
Three questions worth asking before you sign off on any CRM data migration
Does the vendor or agency doing the move know, specifically, what the destination platform does with a record that looks like a duplicate, and can they point to where that platform's own documentation says so? Have they listed which fields or objects are known to degrade on this exact platform pair, instead of a generic "some data may not transfer" disclaimer? And is there a test migration into a sandbox account before the real one, with someone checking the result by hand rather than assuming the import finished means the import worked?
A migration quote that can't answer those three with specifics is quoting the easy part of the job and leaving the agency to absorb the hard part after the client has already signed off. For a build where the destination system is GoHighLevel, our GoHighLevel automation team prices the duplicate-detection and rebuild work up front, in the quote, instead of in a support ticket three weeks after launch.