Most advice on AI document processing starts with a ranked list: fifteen platforms, scored on accuracy, speed, and price per page. Pick the one with the highest number and move on.
That advice optimizes for the wrong variable. The accuracy percentage on a vendor's homepage tells you how often the system gets a field right. It tells you almost nothing about what happens on the pages it gets wrong, and for AI document processing specifically, the wrong answer doesn't look wrong. It looks like data.
TL;DR:
- Traditional OCR fails loudly: a smudged scan produces garbled or blank text a reviewer notices immediately.
- AI document processing adds a reasoning layer, usually an LLM, that can fail quietly by returning a plausible but fabricated value instead of an empty field.
- Published vendor accuracy numbers (like Hyperscience's claimed 99.5%) describe overall correctness, not the split between omission errors and hallucination errors, which carry very different risk.
- Google Document AI's own pricing page charges $30 per 1,000 pages for custom extraction, separate from OCR, which changes the real cost math most roundups skip.
- The decision that matters isn't which vendor scores highest. It's whether your documents are consistent enough for a packaged tool's validation rules to catch its own mistakes.
What AI document processing actually replaces
Before AI document processing, getting data out of a document meant one of two things: someone typing it into a system by hand, or a rules-based OCR template that only worked if the document matched the exact layout it was trained on.
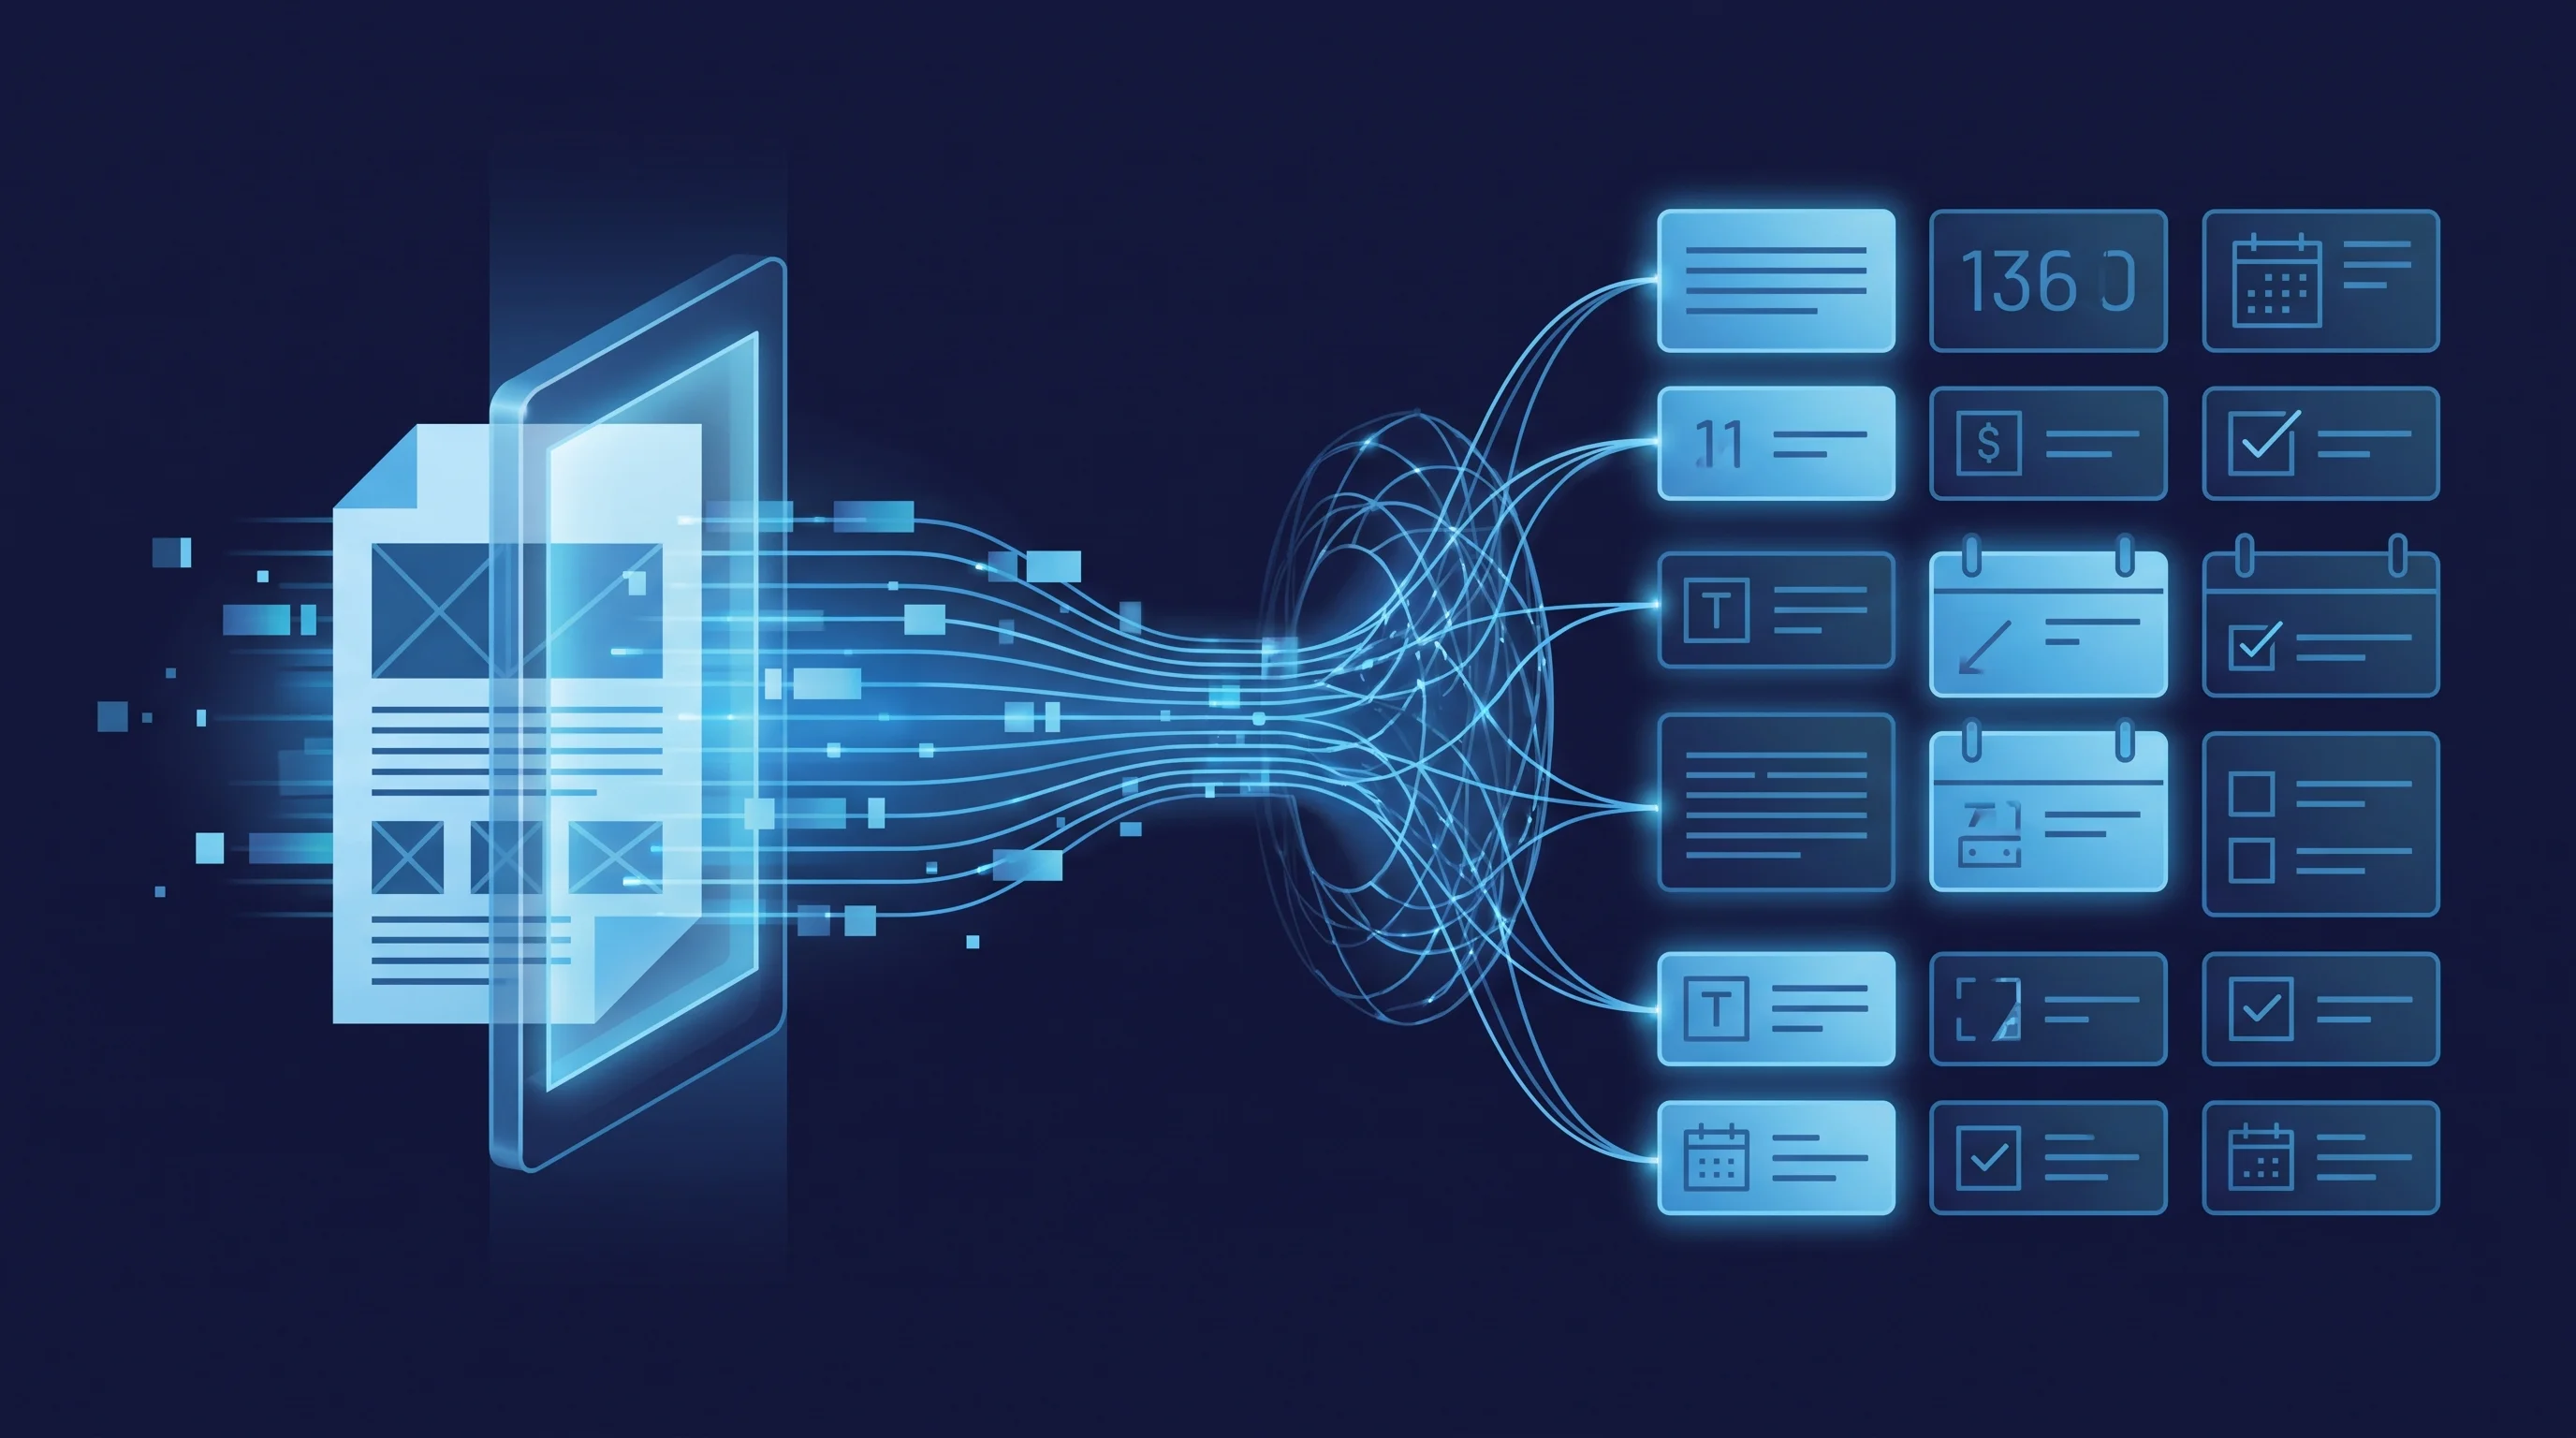
AI document processing, the kind built on large language models and vision-language models rather than rigid templates, can read a document it has never seen before and still find the right field, because it understands context instead of matching pixel positions. That's the entire pitch, and for a lot of use cases, it delivers.
The part that gets skipped is what happens when it's wrong, because "wrong" means something different here than it did with OCR.
OCR fails loudly. LLM-based extraction can fail quietly
Classic OCR has one main failure mode: it can't read the text. A low-quality scan, bad handwriting, or a stray coffee stain produces garbled characters or a blank field. A human reviewer glancing at the output sees the gap immediately, because nothing fills it.
An LLM-based extraction layer introduces a second failure mode that doesn't announce itself the same way. Instead of returning nothing, it can return a confident, well-formatted, completely fabricated value, because the model is trained to produce a plausible answer rather than to admit it doesn't know. Researchers building extraction benchmarks explicitly separate these two error types, calling a missing field an omission and a fabricated one a hallucination, because the two carry different downstream risk profiles: an omission loses information a reviewer will likely catch, while a hallucination can introduce false information that slides straight into your CRM, ERP, or accounting system unreviewed.
This is the number no vendor homepage leads with, because it's harder to market than a single accuracy percentage.
The accuracy number on the pricing page
Vendors do publish accuracy claims, and they're not fabricated, but they're also not the whole picture. Hyperscience's own platform page states that customers regularly achieve 99.5% accuracy and 98% automation, even on handwritten text. That's a real, sourced number, and it's a strong one.
What it doesn't tell you is the composition of the remaining 0.5%: how much of it is a field left blank versus a field filled in wrong. That distinction is exactly what determines how much manual review your workflow still needs, and whether that review is even possible to build, since reviewing for "is this blank" is a five-second glance and reviewing for "is this plausible-looking value actually correct" requires someone to go check the source document every time.
Before choosing a platform on its headline accuracy number, ask the vendor directly how they measure omissions versus incorrect extractions, and whether their own benchmark separates the two. If they can't answer, assume the published number blends both.
The real cost math
Packaged AI document processing is priced per page, and the per-page number usually understates the real bill, because extraction is rarely the only processor you pay for.
As a concrete example, Google Document AI's pricing page lists its Enterprise Document OCR processor at $1.50 per 1,000 pages up to 5 million pages a month, and its custom extractor and form parser processors separately at $30 per 1,000 pages up to 1 million pages, dropping to $20 per 1,000 pages above that. Classification, if you need to sort document types before extraction, runs another $5 per 1,000 pages.
As an illustration of what that stacks up to: a business processing 10,000 invoices a month through OCR, classification, and custom extraction would pay roughly $15 for OCR, $50 for classification, and $300 for extraction, or about $365 a month before any integration, storage, or review-queue work. That's before you've built anything that actually does something useful with the extracted data, which is usually the larger part of the project.
This is the same gap we cover in our guide to AP automation software: the sticker price on a vendor's page is rarely the number that determines whether the project pays for itself.
When a packaged tool is enough, and when it isn't
A packaged AI document processing tool earns its keep fast when your documents are a narrow, consistent type and you only need the output in one or two systems. Standard invoices, W-2s, or a single intake form all fit this pattern well, because the vendor's built-in validation rules were designed around exactly that kind of document.
The case for a custom pipeline shows up once any of these get true:
- Document layout varies a lot. Scanned contracts from a dozen different counterparties, or intake forms that change every time a partner organization updates theirs, strain a vendor's pre-built templates.
- Extracted fields need to update several systems with different rules. A field that's valid for your CRM might fail validation in your accounting system, and a packaged tool usually only enforces one set of rules.
- You need a review step the vendor doesn't support. Routing a low-confidence extraction to a specific person, with the source document attached, is a workflow decision, not an extraction decision, and not every platform lets you build it the way you need.
Our AI automation team builds the extraction and validation layer directly into a client's stack when a packaged tool's rules don't match how their documents actually behave, including the review step that catches a hallucinated field before it reaches an invoice or a contract record.
Where the data goes after extraction
Getting a clean field out of a document solves half the problem. Routing that field to the right system, the right approver, and the right next step is a separate layer, and it's worth treating as one.
If extraction is already reliable but documents still stall before they reach the right person, that's a workflow automation problem, not an extraction problem, and the fix usually looks less like a smarter model and more like a clearer routing path. Our guide to document workflow automation covers that half of the pipeline in more depth.
What to check before you sign a contract
Skip the ranked list and ask three things directly instead:
- What's the split between omissions and hallucinations in your benchmark, not just the overall accuracy number?
- Can your review queue actually flag a plausible-looking wrong value, or only a blank one?
- Do your documents stay consistent enough for the vendor's built-in validation to catch its own mistakes?
A vendor that can't answer the first question clearly is blending the two error types into one headline percentage, and that's the number that was never going to protect your invoices or contracts in the first place.
Tell our AI automation team what your documents actually look like, and we'll scope whether a packaged tool or a custom extraction pipeline keeps the fewest bad values out of your systems of record.